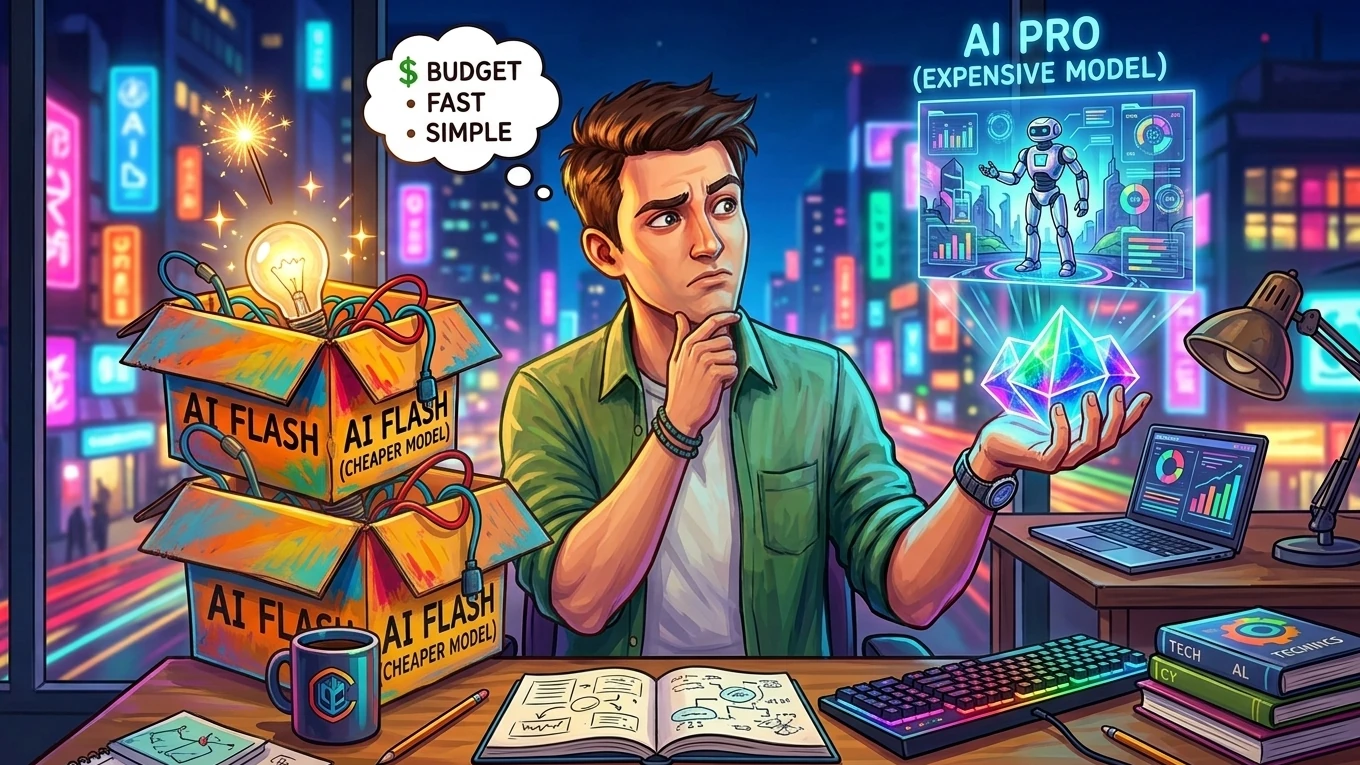
So, on September 22, OpenAI announced two new models: GPT-6 Sol and Luna. They cut API prices in half from the 5.6 series, offering frontier intelligence for everyday work, at different balances of capability and cost. And if you’re like me, your first reaction wasn’t excitement—it was suspicion.
Because the cheapest token isn’t the cheapest result. And that’s the whole conversation nobody’s having.
The real price of a failed run
Let me explain why this matters, in the simplest terms I can.
Most people compare AI models the way they compare gas stations—price per gallon, pick the lowest. That’s fine if every gallon does the exact same thing. But a model isn’t fuel—it’s a worker. And a cheap worker who needs three tries, a supervisor, and two re-dos often costs more than the expensive one who finishes it the first time.
To put it plainly, a smaller model is economical only when escalation, retries, and human correction are counted. A cheap failed run may cost more than an expensive successful one. That’s math most people skip.
So the real question isn’t “which model is cheaper per token?” It’s: which routing reaches the desired result at the lowest total cost? That has to include:
- The output tokens you actually get billed for
- Any tool or agent fees layered on top
- How often the first attempt fails and triggers a fallback call
- The latency cost of retries (especially in real-time systems)
- The review minutes the output demands from a human before it’s usable
That’s what matters at the end of the day. And honestly? Most of the AI pricing comparisons you’ll read online don’t include a single one of those lines.
What the launch actually says
Let’s verify what we know, not what the press releases imply.
OpenAI introduced GPT-6 Sol and Luna as part of a broader 6-series rollout (following GPT-6 Astra earlier in September). The pricing claim is specific: both new models are available at 50% lower cost than the 5.6 promotional pricing. Sol targets demanding coding work, while Luna is the lighter, faster option. There’s no GPT-6 Terra this time, and rightly so.
On DeepSWE v1.1—a software engineering benchmark—Sol came within 1.1 points of Anthropic’s Fable 5 (68.8% at max effort vs. Fable 5’s 69.9% at xhigh effort) at roughly 20% of the cost per task. Luna, at max effort, scored similarly to Claude Opus 5 (not 5.5) and Fable 5 (not 5.1) at medium effort, at a significantly lower cost. Those are OpenAI’s own numbers, though. The benchmark comes from Datacurve, but the comparison chart is OpenAI’s, and the Claude scores were taken from public reports rather than run side by side.
But here’s the twist—and I mean it: those scores don’t tell you what happens in your pipeline. They tell you what happens in a benchmark environment, on predefined tasks, with clean inputs, and no retry logic counted.
Your pipeline isn’t a benchmark. It’s 30 anonymized repository or support tasks, each with its own mess: ambiguous instructions, broken dependencies, partial context, a teammate who already changed half the file.
So the true benchmark that actually matters is testing the model in your workflow. That’s the best way to know if a model suits your requirements, slicing away the “marketing benchmaxxing.”
The cookbook that doesn’t prove production savings
OpenAI’s own cookbook on optimizing agents for cost and quality proposes a routing framework—essentially, send simple steps to smaller models, keep the full model for high-risk cases, and accept savings only when quality holds.
That framework is sound. The evidence it offers is based on synthetic tickets and deterministic simulation. The cookbook’s savings claims ain’t production results—they’re simulated. And that’s important, because it means any recommendation based purely on the cookbook’s numbers is really a theoretical recommendation, not based on your actual workload.
Now, don’t get me wrong. I ain’t saying that you dismiss the cookbook entirely. It’s useful. But it’s useful as a routing method, not a savings proof. A real proof is something readers can reproduce, and if they can’t, it’s just a theory.
As I mentioned earlier, marketing benchmaxxing is unfortunately real. The AI companies compare scores, ignoring retries and human correction time, and call it “cost optimization.” That’s not optimization. That’s marketing math with the hard parts left out.
A routing decision you can actually reproduce
So what should you actually do? Not “use the cheapest model.” Not “always use the smartest model.” Something in between—and something you can measure.
Here’s my proposed method:
-
Define first what’s acceptable for you. Not just “good output.” A set of checkpoints. Does the code compile? Does the explanation cover the three questions the user asked? Does the summary miss any key decision point? Write it down. Without it, “finished” is subjective, and you can’t compare routes fairly.
-
Run 30 real tasks on both routes. Not some fake trial tasks. Real repository commits, real support tickets, real drafts. Repeat each task multiple times—models aren’t deterministic. A single run is a data point. Several runs are a pattern.
-
Count everything. Small-model runs plus escalation calls plus review minutes. Large-model runs plus review minutes (likely fewer, possibly more if the model overproduces). Include the engineering time it takes to maintain the routing logic itself—because routing isn’t free, it costs code and attention.
-
Look for the failure patterns the benchmark misses. More capable models prevent failures that narrow evaluations don’t detect—not because benchmarks are dishonest, but because they’re narrow. A benchmark tests a predefined task. Your pipeline tests reality, which includes unique cases nobody wrote into the benchmark spec.
That’s it. No “best model.” Just a method for deciding what’s best for your workload—which is the only verdict that matters.
The uncomfortable truth
Look, the tech industry wants you to believe there are heroes and villains in AI—that one model is “smarter,” another is “faster,” and choosing between them is a moral act. It’s not. It’s an economics question. And the economics question is more boring and more important than any launch video wants you to believe.
I’ll save you the trouble: the cheapest AI model isn’t the one with the lowest price tag—it’s the one that finishes the job, measured honestly, with retries counted and your time included. Everything else is marketing. And we’ve seen enough of that this year.
Ali Arslan
Ali began his journey as a full-time Tech Journalist in 2021. He’s been a tech enthusiast all his life, starting with a 286 PC gifted to him at the age of 7.
With time, he’s grown into a power user of Android, Linux, Windows, and all things AI, which are the main focus of his writing here at Tech Unbloated. He’s also got a proficient track record for bricking (and sometimes unbricking) Android phones while trying to push the hardware and software to their limits.
Ali has an Advanced Diploma in Business Management from London, UK, and is an English Literature graduate from Punjab University, Pakistan. Other than Tech Unbloated, he’s written for big tech publications like MakeTechEasier, MakeUseOf, How-To Geek, and LimeWire—however, most of his previous work was as a ghostwriter for high-profile clients.
Before becoming a full-time writer, Ali tried his luck at music production, graphic design, teaching, business management, web development, and dropshipping. His writing often reflects all these experiences he’s had in life.
Discussion
Leave a mark
Corrections, disagreements, and the thing I missed. Comments are read before they go up.
No comments yet. Go on — be first, and make it count.
Comments stay off until you say so.
Enable comments in cookie preferences to read and join the thread. No login. No ads in the box.