
Picture a “15 Best Mechanical Keyboards” roundup. Fifteen boards, ranked one through fifteen, with pros and cons under each. Confident tone. Clean comparison table.
Nobody at that publication ever touched a keyboard.
The specs came off Amazon listings. The “pros and cons” were paraphrased from the first few customer reviews. The ranking order came from a spreadsheet sorted by commission rate. That article still sits in the top three, earning commissions.
A disclosure before I go further: Tech Unbloated earns commissions from some links elsewhere on the site. Those relationships never decide what gets recommended or how a list ranks. This article contains no affiliate product links. Read the full Affiliate Disclosure.
Now let me be precise about who this is about, because it matters.
I have peers who are among the best product reviewers working today. They build test benches. They run thermal cameras and colorimeters and week-long battery drains. They buy units at retail so they don’t owe anyone a favor.
They publish the results that make manufacturers stop returning their emails. Those people are the reason I hold the standard I hold—they’re the inspiration for this piece, not the target of it.
And let me kill the obvious misreading right now, because I’m going to spend a whole section on it later: the problem isn’t that somebody wrote about a product they didn’t personally own. That’s an impossible bar, and I’m not going to pretend I clear it. Nobody buys fifteen keyboards.
The problem is the three things stacked on top of each other. Nobody tested anything. Nobody researched anything past the product page. And the order of the list was decided by which merchant pays the biggest cut.
That’s a different business wearing a reviewer’s clothes. And that’s precisely the business model I want to expose and avoid.
The Commission Ladder
Here’s the mechanic almost nobody outside the industry sees.
When a real reviewer builds a “best of” list, the question is which one is best. When a content mill builds a similar list, the question is which item pays the most commission. Those produce different lists, and the second question is much cheaper to answer.
Affiliate networks and publisher dashboards often surface a metric called EPC—earnings per click. Once an editor sorts a spreadsheet by it, the highest earner can slide into the number-one slot, the second gets “best value,” and whatever pays nothing gets the polite mention near the bottom.
The gap between programs can be enormous. Amazon’s US program currently pays 2.5% on PCs and PC components—about $17.50 on a $700 laptop. NordVPN publicly offers 40% on a new annual or two-year subscription, 100% on a new one-month subscription, and 30% on renewals. HubSpot advertises 30% recurring for up to one year. You can check those figures on the companies’ current program pages: Amazon Associates, NordVPN, and HubSpot.
Those rates change, and a generous payout does not prove a recommendation is corrupt. A high-paying product can still be the right choice.
But the incentive exists. And if the same small group of VPNs keeps appearing near the top of list after list, that might be genuine consensus—or it might be several publishers responding to the same payout structure. The disclosure alone can’t tell you which.
The reader thinks they’re looking at a ranking. They may be looking at a rate card.
Why This Got So Much Worse
The incentive has always been there. Three things turned it into an industry.
First, production costs collapsed.
Testing a product properly—running it in real workflows, breaking it, comparing it head-to-head, living with it long enough to hit the annoying stuff—can take 40 to 60 hours in my experience. Even doing the desk work properly, which I’ll defend in a minute, can take a day per category. A mill can produce a fifteen-item roundup in an afternoon.
AI didn’t create the incentive. It made the shortcut cheaper. I’ve already admitted how easily I confuse more tooling with more work in I paid for 23 AI tools. Only 4 produced real work. In publishing, the same mistake scales into a business model.
There’s now a whole tier of tooling built to turn merchant data, customer-review summaries, and a prompt into a formatted roundup. Spec sheet in, article out. The product never enters the building, and neither does the thinking.
The publication can collect the same commission either way. That’s a massive gap in effort for the same revenue. The math doesn’t just tolerate the shortcut—it punishes anyone who doesn’t take it.
Second, the volume drowned out the signal.
This is the part that actually makes me angry. When a mill publishes 200 roundups a quarter, the writer who spent three weeks on one category isn’t competing on quality. They’re competing on output, in a ranking system that has never been great at telling the difference.
The people doing the work get buried under the people who didn’t.
Google has a name for the lowest-value version of this: “thin affiliation”. Its own policy contrasts merchant-copy pages with affiliate work that adds original reviews, rigorous testing, ratings, useful navigation, and real product comparisons.
That distinction is good. The hard part is proving which side of it a confident-looking roundup belongs on.
Third—and this is the uncomfortable one—law and platform policy only address parts of it.
The FTC’s Rule on the Use of Consumer Reviews and Testimonials took effect on October 21, 2024. It bans fake or false reviews and testimonials, bought sentiment, undisclosed insider reviews, fake company-controlled review sites, review suppression, and other deceptive practices. It’s a genuinely useful rule.
It does not automatically ban an editorial list merely because the writer hasn’t personally tested every product. But that does not make implied experience a free-for-all. The FTC says paid endorsers can be liable when they lie about having used a product or about what happened when they used it, and its separate endorsement guidance still requires material relationships to be clear.
Google’s site reputation abuse policy isn’t a general ban on affiliate publishing either. It targets third-party pages exploiting a host site’s ranking signals, while appropriately marked affiliate links are not automatically a violation.
So a first-party list can be disclosed, published, profitable, and eligible to rank while still hiding the one fact readers most need: what determined the order.
That’s the gap.
Hands-On Isn’t the Standard. Honesty About It Is.
Here’s where a lot of writing on this topic goes wrong, mine included until recently.
The easy move is to declare that nobody should recommend anything they haven’t personally used, drop the mic, and walk off. It sounds super principled. It’s also super unworkable, and I think it quietly makes the problem worse.
Nobody buys fifteen keyboards. Nobody subscribes to eleven project-management tools for six months each. A small publication that refuses to publish a list until it has lived with every option on it will simply never publish a list.
Which means the entire category—the exact search result somebody lands on three minutes before they buy—gets handed to the operations that don’t care. An impossible standard isn’t integrity. It’s a gift to content mills.
So let me say the useful thing instead.
Research is legitimate work, and a tech journalist’s research is not the same as a shopper’s research.
When I write up a product I haven’t used, this is what that actually involves:
- Reading the technical documentation rather than the marketing page.
- Pulling the firmware changelog to see what’s been broken and re-broken.
- Finding the panel, chipset, or controller the spec sheet is politely not naming.
- Reading the warranty and return policy, which is where companies tell the truth about what they expect to fail.
- Checking what the refurbished market says about longevity.
- Corroborating across multiple independent reviewers who did test it.
- Weighting the ones with a track record over the ones with a discount code.
- Digging through owner forums for the failure pattern that shows up at month eight, which no launch-week review will ever catch.
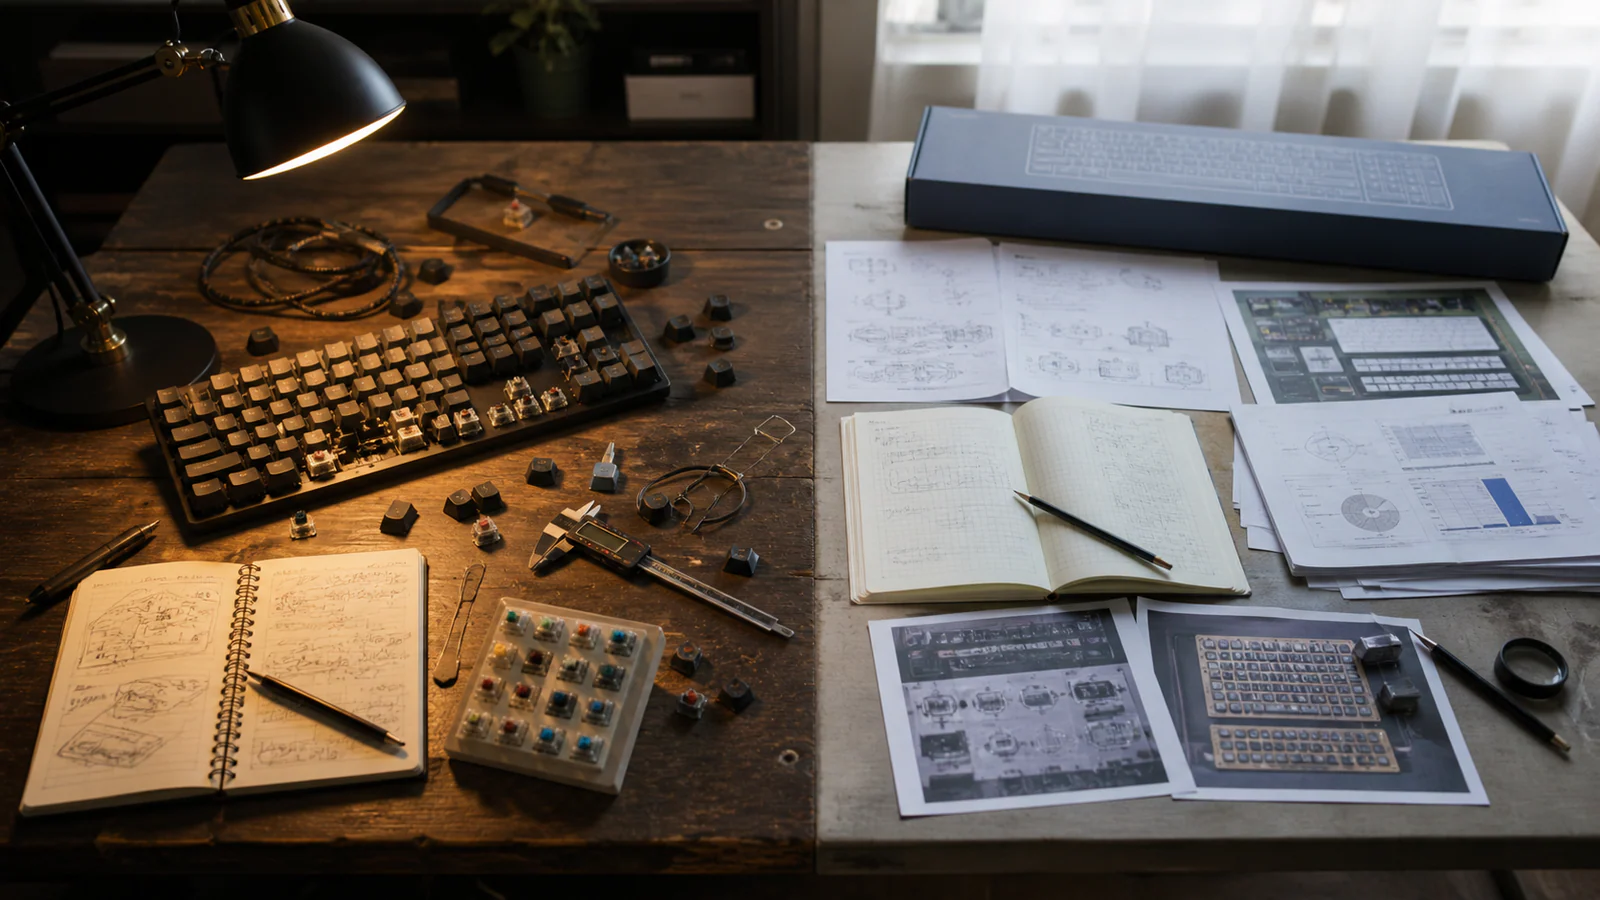
That’s worth something, right? It’s dramatically more than the average buyer has time to do, and it’s a completely different activity from paraphrasing the top three Amazon reviews.
What it isn’t is testing. And the distinction between those two matters enormously to the reader.
So Tech Unbloated does the obvious thing that content mills never do: it tells you which is which.
No badge system, no taxonomy, nothing clever. Every list I publish will say plainly, product by product, whether I’ve used the thing or whether I’ve researched it.
Where I’ve used it, you’ll get the marks of that—version numbers, the specific thing that broke, and screenshots from my desk. Where I haven’t, the entry will say so, and I’ll show you what I’m working from instead: the documentation, the changelog, the warranty terms, the testers I’m leaning on, and why I trust them.
Both are honest work. But only one of them is actual experience, and you should never have to guess which one you’re reading.
Here’s the thing I keep coming back to: if the mills did just this one thing—if they simply admitted, per item, that they’d never touched it and were working from spec sheets—they’d instantly be more credible than they are now. It costs nothing. No testing budget, no review units, no extra hours.
They don’t do it because the whole product depends on you believing there’s more behind the ranking than there is.
The dishonesty was never the desk research. It’s the implied experience that isn’t there.
Where Tech Unbloated Stands
I started this publication because I was tired of the alternative. why more productivity tools can make you less productive explains the wider version of the problem. This is what happens when the same appetite for more tools, more output, and less friction takes over the recommendation business.
And here’s the confession part: I contributed to it. Early on, before I fully understood what I was feeding, I wrote entries for lists like the ones I just described. I was handed the products and the order and asked for 150 words each.
I told myself I was writing copy, not reviews. That distinction was doing a lot of work it hadn’t earned.
Note what I was handed, though. Not just the products. The order.
So here’s the one hard rule this publication runs on, the one I’d want you to hold me to above everything else:
Commission rates play no part in the order. Ever.
Not as a tiebreaker. Not as a nudge on close calls. Not as a quiet thumb on the scale when two options are genuinely comparable and one of them pays eight times better.
The ranking answers one question—which of these should you actually buy—and the payout table isn’t in the room when that gets decided.
Where the highest-paying option isn’t the best one, I’ll say so inside the entry rather than burying it. And you’ll see me put products with no affiliate program at all above ones that pay me, often enough that you can check my work.
If that never happens on this site, something’s wrong, and you should say so.
The FTC’s endorsement guidance says material connections should be clear and conspicuous. I comply. But disclosure is the floor, not the ceiling.
Every mill on the internet can disclose. It costs almost nothing, and it tells you nothing about whether the money moved the list.
The Part I Don’t Like Admitting
Here’s where I make myself uncomfortable.
Specific negatives can make a recommendation feel more credible. And credibility can sell. Which means there’s a version of honest reviewing that’s just superior affiliate strategy wearing a nicer coat.
I can’t prove to you I’m not doing that. Nobody in my position can.
What I can do is leave evidence and make the evidence expensive to fake. Naming what I tested and what I didn’t costs me the option of implying more than I know. Ranking against the payout costs me money on every list where I do it.
Those aren’t claims about my character—they’re constraints you can watch me operate under and catch me breaking.
Five Signals That Separate an Honest List From a Rate Card
You don’t have to take any of this on faith. These are the checks I use, and most readers have never been told to look for them.
Note what’s not on this list: “Did they test everything?” They almost certainly didn’t, and that alone tells you nothing.
1. Check whether the ranking tracks the payout
This is the fastest tell there is. Open the same category on five different sites. If the top three products are identical and in the same order, don’t assume five teams independently reached the same conclusion.
It might be legitimate consensus. It might be five publishers responding to the same incentive structure. Now you know to inspect the method.
Then check what’s missing. Most categories have a well-regarded option with no affiliate program at all. If a list of “the 15 best” somehow excludes the thing enthusiasts actually recommend in forums, ask whether it got ruled out on merit or on payout.
2. See whether they tell you what they actually know
This is the big one, and almost nothing on the open web passes it.
An honest list distinguishes between the products the writer used and the ones they read about. It’ll say it outright—“I’ve run this one for six months,” or “I haven’t used this, but the spec sheet and two teardowns line up.”
That admission costs the writer something, which is exactly why it matters. If all fifteen entries are written in the same confident register, with the same depth of detail, that tells you something.
No one has the same depth on fifteen products. Uniform confidence across a long list means the confidence is manufactured.
3. Look for the details only contact produces
Version numbers, firmware revisions, exact SKUs, and the specific plan tier. Real testing produces these. So does real research—if you read the changelog, you know the build number.
Either way, they’re expensive relative to what a mill spends. A roundup that says “Notion” without the plan, the interface version, or the workflow it was judged on didn’t come from testing or research. Nobody opened anything, including the documentation.
4. Find the alternative they passed on
Every honest “best of” is also a rejection list. Whoever picked A over B can tell you why B lost—and can do that from research alone, because ruling something out on specs, pricing, or a known defect is legitimate work.
If a piece can’t articulate what got excluded and why, if everything on the page is a winner in its own special little category, no comparison happened. They did recommendations, not comparisons.
5. Check whether the images match the claim
Press-kit photography isn’t a crime. If an entry says the writer is working from research, manufacturer images are the honest choice.
The tell is the mismatch: studio-perfect marketing renders sitting under language that implies hands and hours. Real use looks like a desk—too many tabs open, an off-center crop, a notification badge in the corner.
Polished images plus first-person testing language is the combination to distrust.
Bonus: read the disclosure, then read past it. Disclosure tells you that money exists. What matters is what it moved. Free unit? Early access? Did the company approve the draft before publication? Did commission rates affect the ranking?
Nobody discloses that last one, and it’s the only one that would really tell you something.
The Ask
I don’t expect you to trust me because I wrote this.
Trust is earned in the details, and the details live in the lists themselves, not in essays about lists. Read the Tech Unbloated pieces. If an entry doesn’t make clear whether I used the thing or researched it—call it out. If the ranking ever looks suspiciously like the payout ladder, call that out louder.
There are comments. There’s an email address. I would rather be corrected in public than let a weak piece stand.
Then apply the same five checks everywhere else. Not to the reviewers doing real work—those people need your clicks more than the mills do, and they’re the ones the volume is burying. Apply them to the ranked lists that surface when you’re three minutes from buying something.
Because the economics won’t fix this from the inside. The FTC can ban fake reviews; it can’t make every publisher say what they haven’t done. Google can identify thin affiliation; it can’t show you whether a payout table decided the order.
The gap between those two things is where this entire industry lives.
Nobody’s coming to close it. You’re the enforcement mechanism, and there isn’t another one.
Ali Arslan
Ali began his journey as a full-time Tech Journalist in 2021. He’s been a tech enthusiast all his life, starting with a 286 PC gifted to him at the age of 7.
With time, he’s grown into a power user of Android, Linux, Windows, and all things AI, which are the main focus of his writing here at Tech Unbloated. He’s also got a proficient track record for bricking (and sometimes unbricking) Android phones while trying to push the hardware and software to their limits.
Ali has an Advanced Diploma in Business Management from London, UK, and is an English Literature graduate from Punjab University, Pakistan. Other than Tech Unbloated, he’s written for big tech publications like MakeTechEasier, MakeUseOf, How-To Geek, and LimeWire—however, most of his previous work was as a ghostwriter for high-profile clients.
Before becoming a full-time writer, Ali tried his luck at music production, graphic design, teaching, business management, web development, and dropshipping. His writing often reflects all these experiences he’s had in life.
Discussion
Leave a mark
Corrections, disagreements, and the thing I missed. Comments are read before they go up.
No comments yet. Go on — be first, and make it count.
Comments stay off until you say so.
Enable comments in cookie preferences to read and join the thread. No login. No ads in the box.